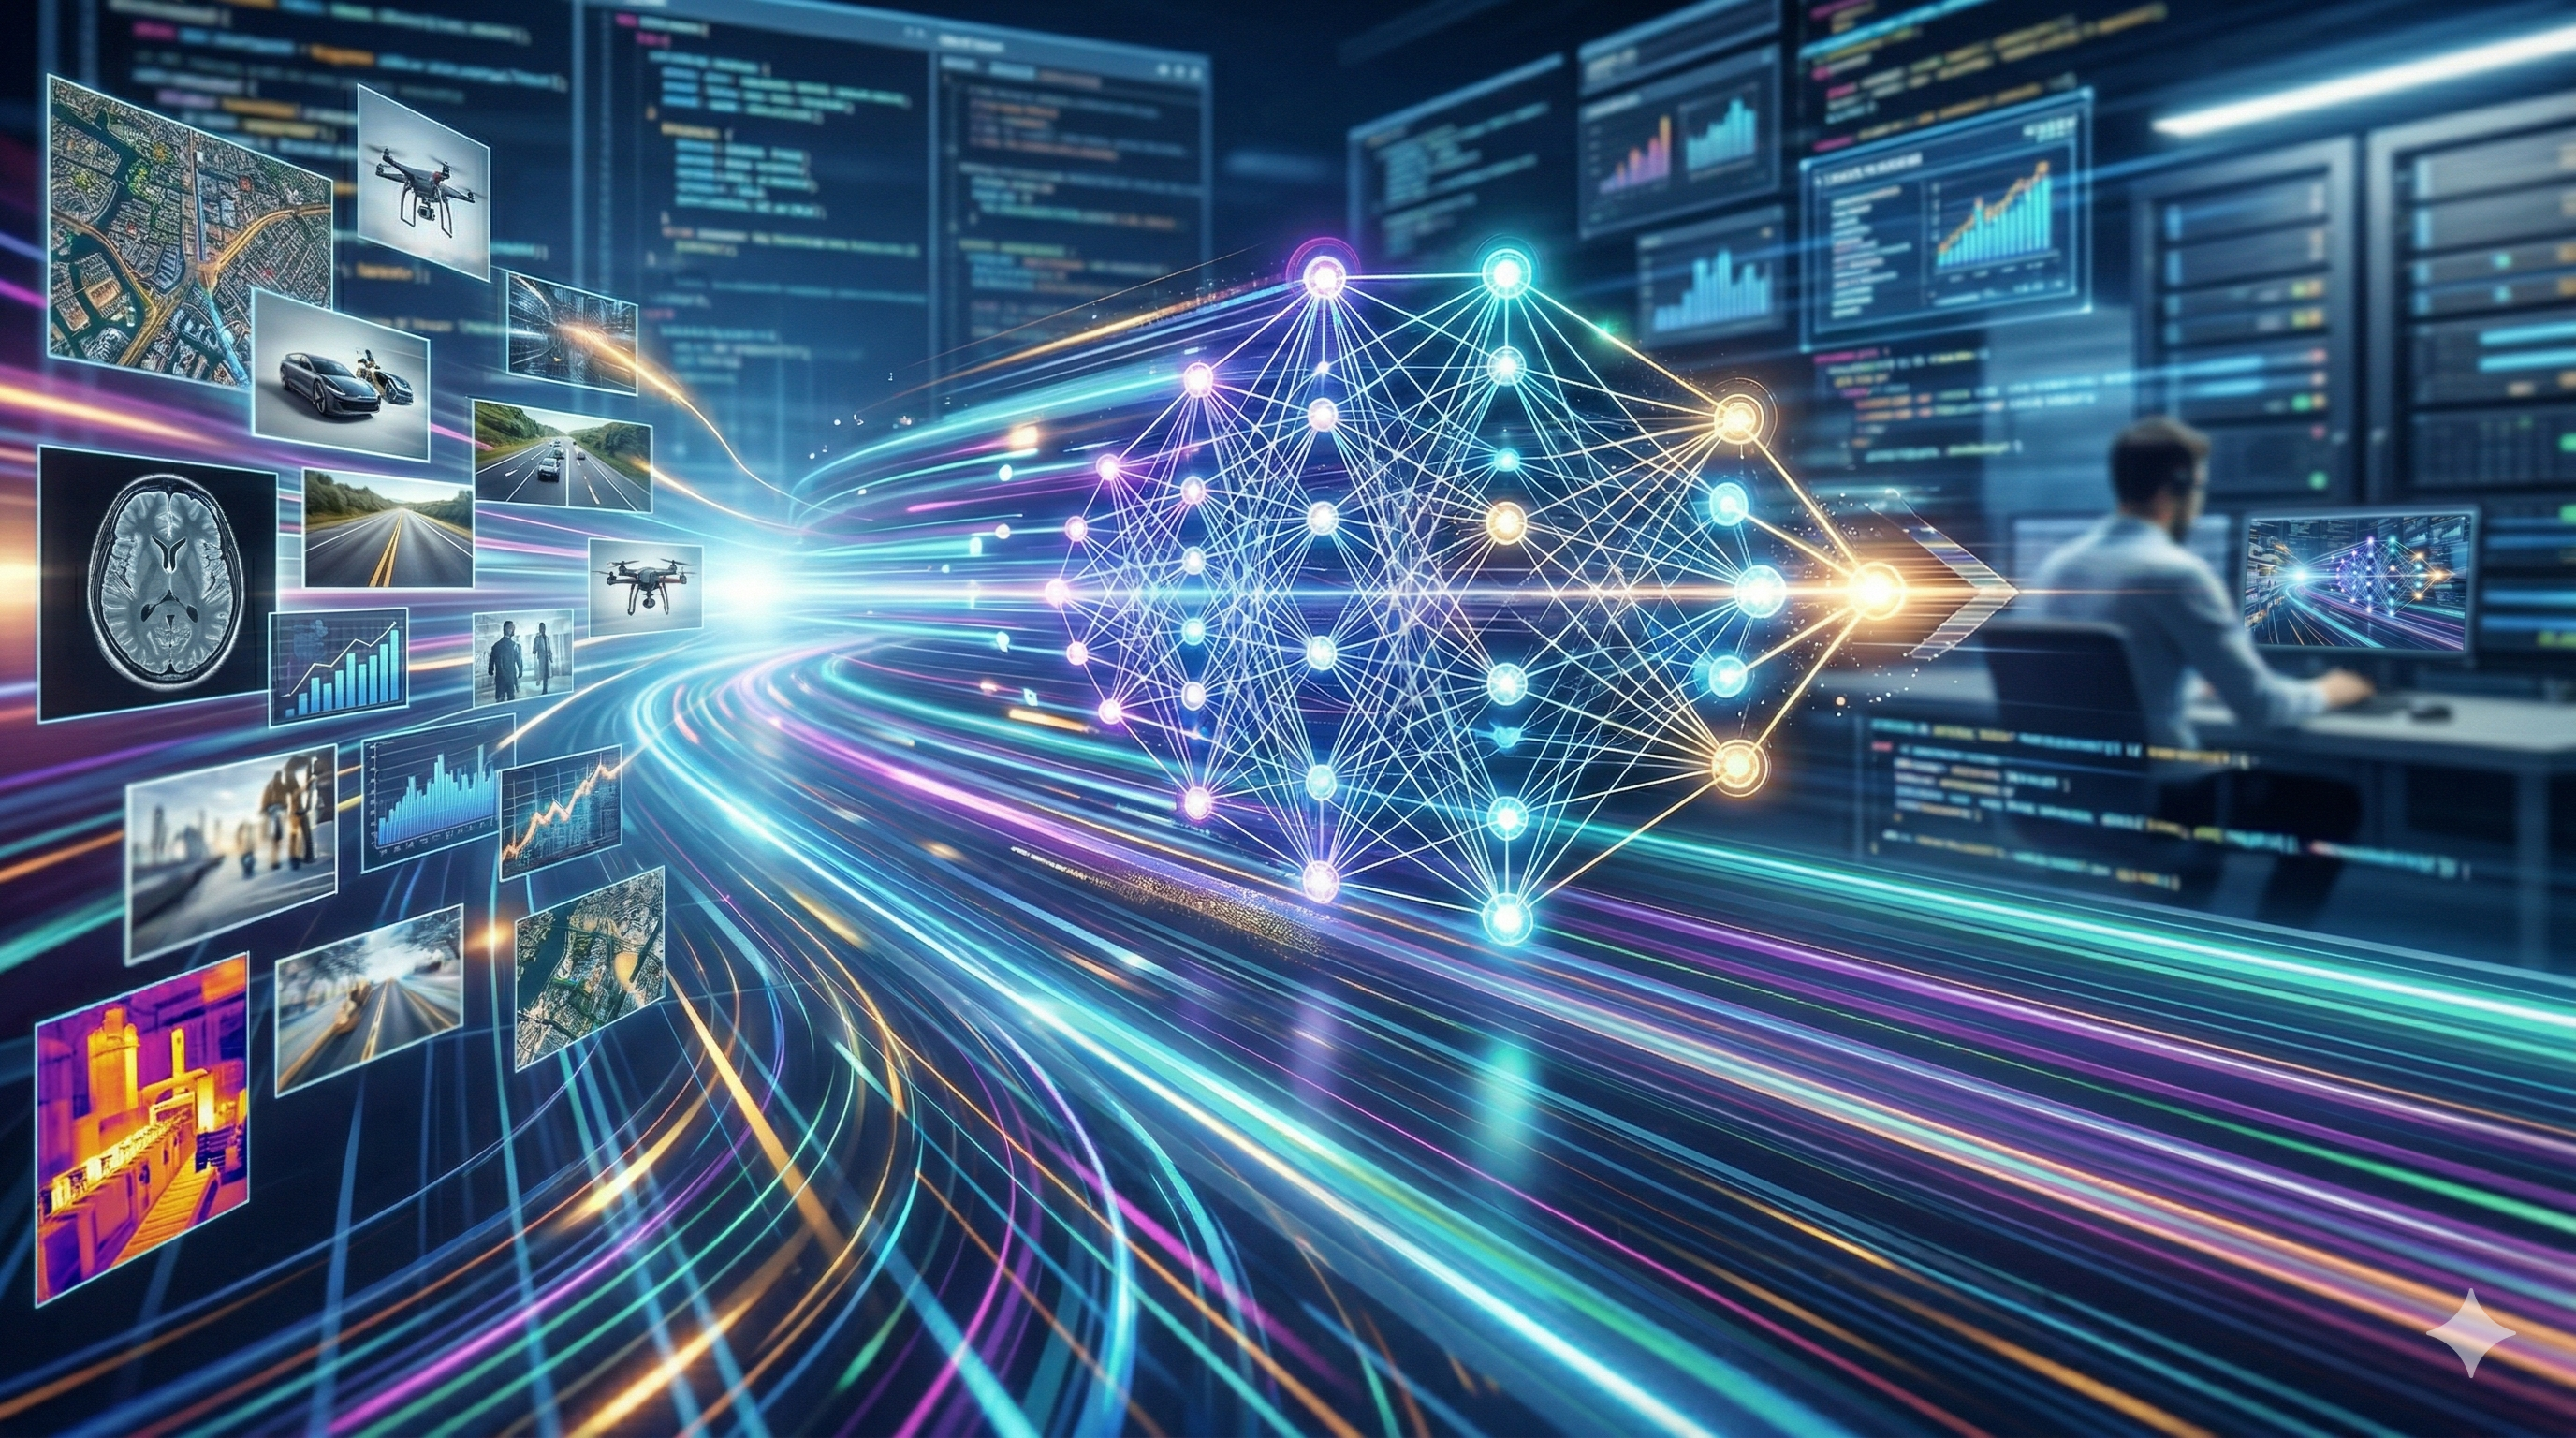
Overview
Modern vision-language models process hundreds of visual tokens per image, which makes them powerful, but also expensive.
IVTP reduces this cost by pruning unnecessary tokens while still keeping the important ones.
- ◆~47% less computation
- ◆~89% fewer tokens
- ◆~1% accuracy loss
The Problem
Images are split into hundreds of tokens.
Most of them are irrelevant.
- ◆Question: "What is the dog doing?"
- ◆Model still processes the sky, grass, and background
This ends up wasting compute.
The Core Idea
IVTP makes pruning instruction-aware.
Instead of just keeping visually important tokens, it keeps the ones that are relevant to the user’s prompt.
Two-Stage Pruning
1. Visual Pruning (ViT) - Removes visually redundant tokens
2. Instruction-Guided Pruning (LLM) - Uses prompt relevance - Keeps only the useful tokens
Architecture (Visual Breakdown)
- ◆Token pruning approaches
- ◆IVTP pipeline
- ◆Performance vs compute
Key Results
- ◆~46.8% compute reduction
- ◆~88.9% token reduction
- ◆~1% accuracy drop
IVTP outperforms other pruning methods at the same compute level.
Slide-by-Slide Explanation
My Notes & Breakdown
Final Takeaways
- ◆Smarter pruning > more compute
- ◆Instruction-aware systems win
- ◆Massive efficiency gains without retraining
View Research Paper
Read the OFFICIAL Alibaba Research Paper
 MDCran·Dec 3, 2025·1 min read